How We Cut Regression From 90+ Minutes to 8
Our regression suite used to take 90 to 120 minutes to tell you it was red. Today it runs in about 8. Here's how we got there.
Nobody wants to use it#
When I took over the testing, nobody wanted to use it, and for good reasons. Let's quickly dive into each of them.
Flakiness#
We've all had the experience of doing the exact same thing three times and getting a different result each time. That's what flakiness feels like.
You run the test once, 6 fail. You run it again, 1 fails. You run it the third time, hope for the best, and a different one fails.
If you can't trust the results, what's the point of running it?
Slow runtime#
It took regression 90 to 120 minutes to finish. 30 minutes just to cover the basics (smoke).
If the first run failed and you had to run it again, you could easily lose multiple hours. Nobody has time for that.

Debugging#
A test fails only in CI and you can't see why.
Without paying for Cypress Cloud, your options are limited. It was a great experience locally, but CI was a pain in the ass. We constantly had issues with storing screenshots, and those who have debugged stack traces know how fun it is.
(It isn't.)
Let's try to fix it#
My first instinct was to try to fix it.
Flakiness#
I spent a lot of time debugging and hardening the suite. Some of the fixes were in the tests, and some exposed real UX gaps in the product.
Smoke got stable and regression became more trustworthy, though not fully. The real issue was that maintenance never stopped. I analyzed results every day and looked for ways to make it more robust.
Runtime#
Then I attacked the runtime.
By splitting the suite into ten parallel CI jobs, regression got down from 90+ to 30–40 min, but we maxed out our CI jobs.
More about GitLab's parallel:matrix.
Debugging#
Even after adding videos to CI artifacts, debugging was still hard.
The idea was that the combination of a video and a stack trace would make it easier, but it didn't. Colleagues complained that it was really ineffective, and they were right. Especially when our GitLab runners hit the ceiling and dropped the recording.
You'd look for a fail at the invitation step, but the video was stuck at the login page.
Playwright time!#
Then I tried a Playwright proof of concept. The goal was simple: get faster runs and more reliable results in two weeks.
I started with the smoke tests.
Runtime#
We immediately cut the smoke runtime by more than half (~ 5min) simply because Playwright supports parallel runs natively.
Devil's advocate#
Cypress community has some cool solutions like cypress-parallel and sorry-cypress if you want to stay in that ecosystem.
sorry-cypress replaces the paid Cypress Cloud, but then you have to run your own infra, and in our setup we still needed more CI containers than Playwright because Cypress doesn't have in-process workers.
While cypress-parallel doesn't require additional infra, the same goes for resources. Each Cypress process spins up the Electron app + a Node traffic proxy + the browser, while Playwright has just a thin Node process talking to the browser.
Debugging#
Debugging finally got easy. You get all the standard browser dev tools like Console, Network, Sources, and more. It now takes minutes to find out why a test failed.
If you still haven't, head to trace.playwright.dev.
If you don't have a failed test trace, I'll send you one. I have plenty!
Flakiness#
Cypress smoke tests rarely flaked, so the migration was only a slight improvement in this area.
The final boss!#
After the successful PoC that yielded a fast, reliable, and easy-to-debug suite, the decision was easy — let's migrate the whole suite to Playwright.
Flakiness#
Flakiness went down a lot.
Playwright's browser-control model meant we could get rid of several Cypress-specific workarounds. We said bye-bye to Puppeteer plugins to test SSO, iframes and shadow DOMs were no longer special cases, and we stopped worrying that the next Cypress bump would break our two implementations of copy-to-clipboard (local and CI).
We also used primitives like page.addLocatorHandler to handle unexpected dialogs and expect.toPass for parts we knew had to pass.
We had that one input that always flaked. I've tried plenty of "more robust" ways of interacting with it, but nothing helped.
It doesn't happen anymore.
Runtime#
Tests started failing because no email was found. When I realized I had hit the email throughput limit, I knew I was onto something. The limit is roughly 11 emails/min per domain. The tests were "too fast". I solved it by creating more email inboxes.
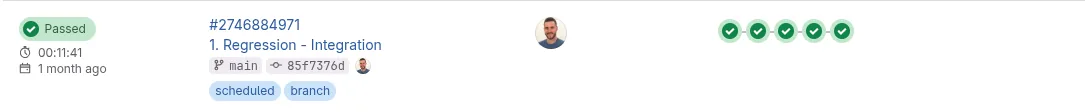
With 10 CI jobs × 4 workers, we got regression runtime from 90+ min to about 8 min.
Takeaways#
- Contact DevOps for proper runner allocation
- Fable was great for distributing tests across jobs based on duration. With Playwright, some jobs took 10+ minutes while others finished in 5–6 because our tests have very different durations.
- Four months later, I'm still happy with the results. A new healthy base with minimal maintenance freed up time for increasing coverage.
- Almost all teams switched over to Playwright since then.
- I'm not going back to Cypress.